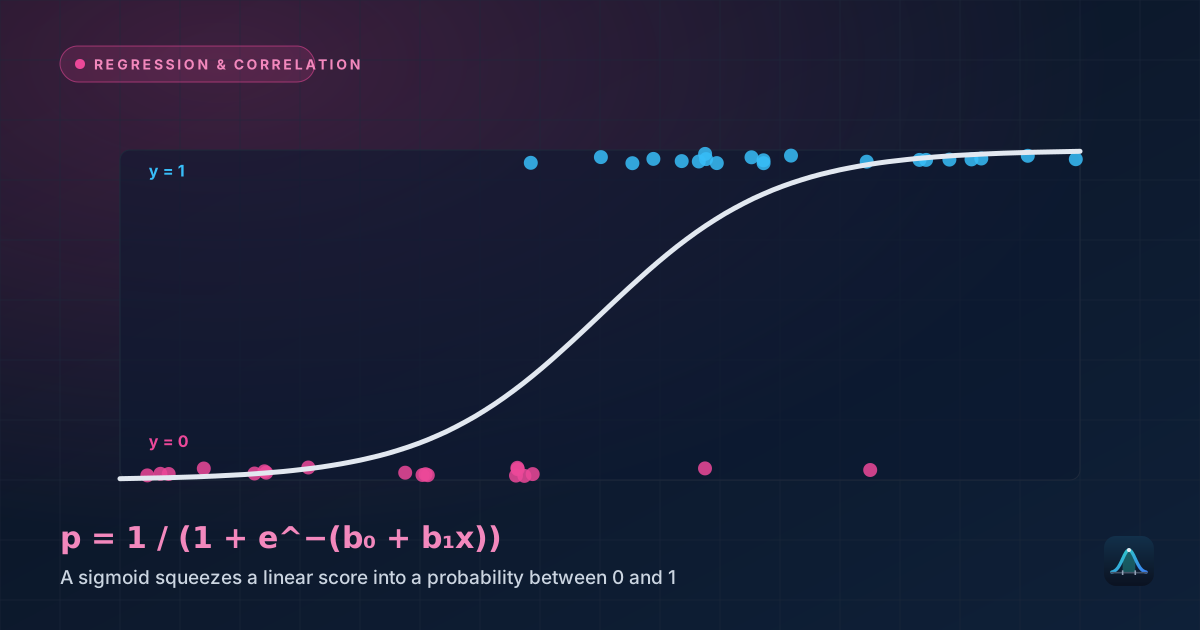
Logistic regression handles a binary outcome — exactly two categories. Plenty of real prediction problems have more than two unordered outcomes: which of three products a customer buys, which of several political candidates a voter supports, which treatment a patient responds best to. Multinomial logistic regression extends the same underlying framework to handle any number of unordered categories at once, using the same maximum-likelihood machinery under the hood.
- How the model generalizes binary logistic regression using a baseline category
- A full worked example converting fitted coefficients into predicted probabilities
- How to interpret a coefficient as a relative risk ratio
- When multinomial logistic regression is the right choice versus its alternatives
The Baseline Category Approach
With more than two categories, there's no single log-odds to model the way binary logistic regression does — instead, multinomial logistic regression picks one category as a baseline (a reference point) and models the log-odds of every other category relative to that baseline, one separate equation per non-baseline category:
Each non-baseline category j gets its own full set of coefficients. With 3 categories total, this means 2 separate equations (each comparing one category against the shared baseline); with 4 categories, 3 equations, and so on — the number of equations is always one less than the number of categories.
Worked Example: Predicting Product Choice
Problem: A retailer models which of three products (A, B, or C, with C chosen as the baseline category) a customer selects, based on the customer's age (in years, centered so that x=0 represents an average-age customer for simplicity). The fitted model gives: for Product A vs. C, b₀=0.2, b₁=−0.05; for Product B vs. C, b₀=−0.3, b₁=0.08. For a customer at the average age (x=0), find each product's predicted probability.
At x=0, each equation's linear part reduces to just its intercept: log(P_A/P_C) = 0.2, so P_A/P_C = e^0.2 ≈ 1.221. log(P_B/P_C) = −0.3, so P_B/P_C = e^(−0.3) ≈ 0.741.
Since the three probabilities must sum to 1, and both ratios are expressed relative to P_C, set P_C = 1 (as a reference weight) and scale: weights are 1.221 (A), 0.741 (B), and 1 (C), summing to 2.962.
P_A = 1.221/2.962 ≈ 0.412 P_B = 0.741/2.962 ≈ 0.250 P_C = 1/2.962 ≈ 0.338
For an average-age customer, the model predicts roughly a 41.2% chance of choosing Product A, 25.0% for Product B, and 33.8% for Product C — three probabilities that, as required, sum to exactly 1.
Interpreting a Coefficient as a Relative Risk Ratio
Exactly as in binary logistic regression's odds ratios, exponentiating a multinomial coefficient gives a relative risk ratio: how the odds of choosing that category over the baseline change per one-unit increase in the predictor. For Product A vs. C: e^(b₁) = e^(−0.05) ≈ 0.951 — each additional year of age (above the centered average) is associated with the odds of choosing A over C dropping to about 95.1% of what they were, a modest decline. For Product B vs. C: e^(0.08) ≈ 1.083 — each additional year is associated with the odds of choosing B over C rising by about 8.3%. Age pulls preference in opposite directions for these two products relative to the baseline, information the raw predicted-probability numbers alone don't make as explicit as the relative risk ratios do.
Choosing the Baseline Category
The choice of baseline category doesn't change the model's actual predictions — the same fitted probabilities emerge regardless of which category is chosen as the reference point — but it does change how the coefficients themselves are most naturally interpreted. Choosing the most common category, or the most practically relevant one for comparison (like an existing product line, when studying customer adoption of new options), typically makes the resulting coefficients easiest for a reader to interpret directly.
When to Use Multinomial vs. Its Alternatives
Use multinomial logistic regression when the outcome categories are genuinely unordered — product choice, candidate preference, which of several unrelated diagnoses a patient has.
Use ordinal logistic regression instead when the categories have a natural order (a satisfaction rating from poor to excellent, a disease stage from mild to severe) — a model built specifically to respect that ordering, rather than treating the categories as unrelated the way multinomial logistic regression does.
Use ordinary binary logistic regression when the outcome genuinely has only two categories — multinomial logistic regression reduces exactly to binary logistic regression when there are only 2 categories total, so no separate method is needed for that simpler case.
Real-World Uses
Marketing and customer segmentation: as in the worked example, predicting which of several product options, subscription tiers, or marketing offers a customer is most likely to choose, based on demographic or behavioral predictors, is one of the most common applications of multinomial logistic regression in business analytics.
Political science and voting behavior: modeling which of several candidates or parties a voter is likely to support, based on demographic and attitudinal predictors, is a textbook application — the unordered, multi-category nature of candidate choice fits the model's assumptions directly.
Medical diagnosis modeling: predicting which of several distinct, unrelated diagnoses is most likely given a patient's symptoms and test results is a natural fit whenever the possible diagnoses don't have a meaningful severity ordering among them.
Common Mistakes
Treating the outcome as ordinal when it's genuinely unordered, or vice versa. Fitting an ordinal model to genuinely unordered categories forces an artificial ranking onto categories that don't have one; fitting a multinomial model to genuinely ordered categories ignores real information about that ordering that a properly chosen ordinal model would use more efficiently.
Forgetting that coefficients are always relative to the chosen baseline. A coefficient's sign and size only make sense in the context of "relative to the baseline category" — comparing coefficients across different baseline choices, without converting them onto a common reference, produces a meaningless comparison.
Does multinomial logistic regression require more data than binary logistic regression?
Is multinomial logistic regression fit using maximum likelihood, like binary logistic regression?
Can multinomial logistic regression be evaluated the same way as binary logistic regression?
What's the independence of irrelevant alternatives assumption?
Share this article
Written by
Statistics Fundamentals Editorial Team
Written and reviewed by our team of statistics educators. Content is aligned with GCSE, A-Level, AP Statistics, and undergraduate curricula.
About Statistics Fundamentals →